For years, the default AI interface has been simple: give a model tokens and ask it to generate more tokens. That works when the destination is a person—a reply, explanation, draft, or piece of code.
But much of software does not need another paragraph. It needs a decision: which team owns this ticket, how urgent is it, or should a result be reviewed?
That is the problem Jev is built for. TypeSafe AI calls it its first public System One Model: a model designed to return typed decisions and probabilities that software can use directly, rather than open-ended prose. Jev was introduced in September 2026 and is in early access. TypeSafe's announcement describes the approach.
The gap between an answer and an action
A conventional LLM can return JSON, call a tool, or follow a schema. That is often exactly the right solution. Still, the model generates a sequence of tokens; the application must decide whether the result is valid and what to do with it.
flowchart LR
A["Application state"] --> B["Generative model"]
B --> C["Generated output"]
C --> D["Parse and validate"]
D --> E{"Usable?"}
E -->|Yes| F["Application action"]
E -->|No| G["Retry or review"]
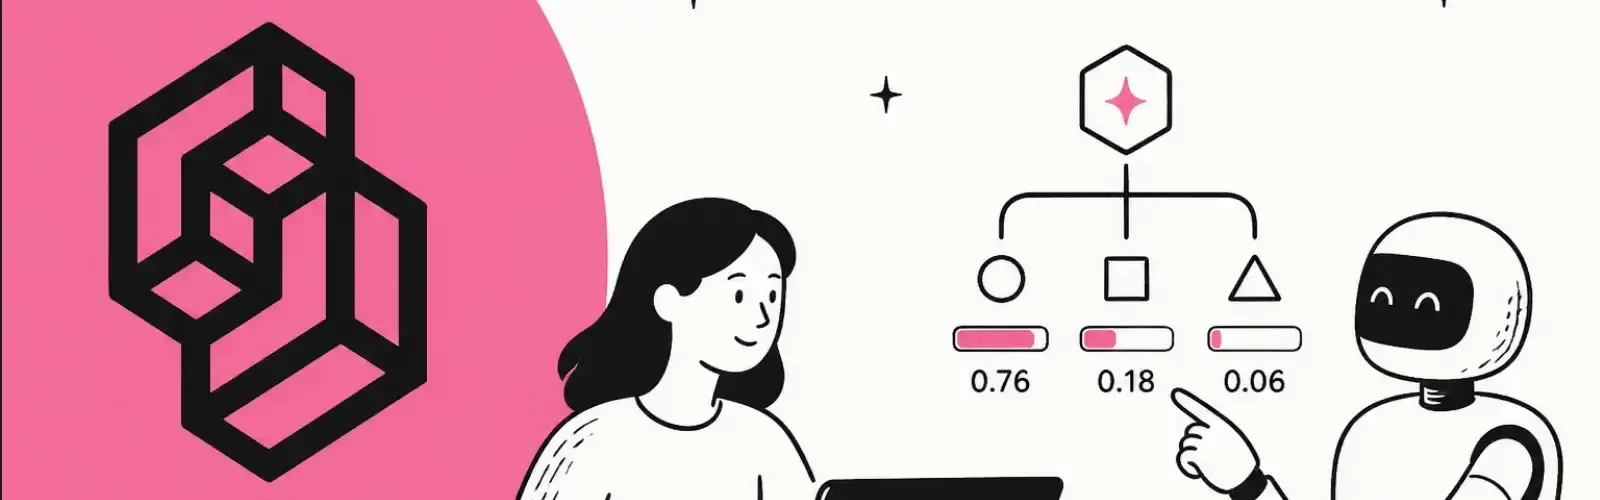
Jev changes the shape of the question. The developer defines possible answers before inference. The model returns a choice, score, or yes/no probability within that space. Code still owns the action.
flowchart LR
A["Application state"] --> B["Jev"]
C["Typed questions"] --> B
B --> D["Decision and probabilities"]
D --> E{"Application policy"}
E -->|Confident enough| F["Act"]
E -->|Uncertain| G["Review or ask again"]
This is not a claim that an LLM cannot produce structured output. It is a different optimization target: use a model for bounded judgments, then let ordinary code handle the workflow.
Three kinds of question
TypeSafe currently documents three decision primitives: Choice, Score, and Noul.
Choice: which option fits?
Imagine a support ticket: “The app crashes whenever I try to pay.” The application could ask which team should receive it: billing, engineering, account, or other.
A Choice returns a selected option, a probability for every option, and a confidence value. This illustrative response is not a live Jev result:
{
  "choice": "engineering",
  "probabilities": {
    "billing": 0.14,
    "engineering": 0.78,
    "account": 0.03,
    "other": 0.05
  }
}
The useful detail is not just engineering. The application can see that billing remains plausible and decide whether to notify both teams or request human triage.
Score: where on a scale does it fall?
Some decisions are ordered rather than categorical: severity, urgency, relevance, or quality. A Score rates the state against developer-defined levels, such as cosmetic, degraded but usable, and blocking. The result can fall between levels; the model also returns probabilities and confidence. The scale and its meaning belong to the application, not to a universal definition of “urgent.”
Noul: how likely is “yes”?
A Noul asks a yes/no question and returns the probability of “yes.” For example: “Does the evidence in this ticket support an automatic refund?” The code can then require review using a threshold chosen for that workflow.
The shared pattern is state in, bounded answer out. The application must still decide what risk it is willing to accept.
A concrete workflow: ticket triage
Consider a support system that needs to route and prioritize a ticket. Instead of asking one model to write an entire plan, the software can ask narrow questions and keep the workflow explicit.
flowchart TD
A["Incoming ticket"] --> B["Choice: owning team"]
A --> C["Score: urgency"]
A --> D["Noul: needs human review?"]
B --> E["Code checks answers and policy"]
C --> E
D --> E
E -->|Routine and clear| F["Route automatically"]
E -->|Urgent| G["Priority queue"]
E -->|Ambiguous| H["Human triage"]
The model contributes judgment; the program remains responsible for thresholds, retries, escalation, audit logs, and final actions. That separation matters when a decision is made repeatedly inside production software rather than read once by a person.
Jev beside an LLM, not instead of one
Jev does not need to write the final response. A language model may still be the best tool for research, code, explanation, and conversation. Jev can sit at the points where the system needs to route or evaluate.
flowchart LR
U["User request"] --> J1["Jev: classify intent"]
J1 -->|Research| R["Research agent"]
J1 -->|Coding| C["Coding agent"]
J1 -->|Support| S["Support agent"]
R --> L["LLM: generate response"]
C --> L
S --> L
L --> J2["Jev: evaluate result"]
J2 -->|Accept| P["Code applies policy"]
J2 -->|Retry| L
J2 -->|Escalate| H["Human review"]
A useful shorthand is LLMs generate, Jev judges, and code acts. It is an architectural pattern, not a rule every application should adopt. If a single structured-output LLM call already meets your latency, cost, and reliability targets, an extra model may add needless complexity.
Why not just ask an LLM for JSON?
JSON mode, tool calling, and constrained schemas are real alternatives. They can make generative outputs reliably parseable, and many applications should start there.
TypeSafe's argument is that formatting is only part of the problem. Jev is designed around parallel, typed decisions with probability distributions, whereas a conventional LLM generally generates tokens sequentially. The company also trains Jev with what it calls Reinforcement Learning for Calibrated Decisions (RLCD). These are TypeSafe's architectural and training claims, not proof that Jev will outperform an LLM in every workflow. Its technical announcement sets out the distinction and caveats.
The difference is worth testing where decisions are frequent, narrow, and latency-sensitive. It matters less where the task is open-ended writing or the model must invent an answer outside a predefined set.
Probability is not the same as correctness
Suppose a system reports an 80% probability for an outcome many times. Calibration means that, across comparable cases, roughly 80% of those outcomes should occur. A single 80% prediction can still be wrong.
TypeSafe also reports a confidence value. For a Choice, the docs describe it as a measure of how concentrated or spread out the option probabilities are. It is not a universal “safe to automate” switch. Your application needs thresholds appropriate to its own costs of false positives and false negatives. See TypeSafe's confidence guide.
That distinction tempers the phrase “no hallucinations.” A typed output can rule out an invalid option or malformed schema, but a well-typed decision can still be factually wrong. TypeSafe discusses limitations in its Jev 1.13 jaggedness notes.
What I would test before using it in production
- Accuracy on your own cases: compare Jev with your current structured-output LLM and a simple rules baseline.
- Calibration: group decisions by reported probability and check observed outcomes, not just top-choice accuracy.
- Escalation: decide what happens when the model is uncertain, options are incomplete, or input is out of distribution.
- End-to-end latency and cost: include network time, validation, retries, and human-review rates—not only model inference.
- Failure boundaries: keep authorization, irreversible actions, and business rules in deterministic code.
TypeSafe reports substantial speed and cost advantages on its own System One workflow evaluations, while noting how those benchmarks were designed and where bias might remain. Treat those figures as company-reported results until reproduced on workloads resembling yours. The published workflow evaluations are a starting point, not a substitute for a private test.
The bigger idea
Many production AI problems are not writing problems. They are routing, scoring, classification, verification, and gating problems wrapped in prompts.
Jev is an attempt to make those judgments a first-class software primitive. Its strongest use is not replacing every LLM call; it is making the boundary between generation, decision, and action explicit. Whether that improves your system is an engineering question worth measuring.
Sources and further reading
For years, the default AI interface has been simple: give a model tokens and ask it to generate more tokens. That works when the destination is a person—a reply, explanation, draft, or piece of code.
But much of software does not need another paragraph. It needs a decision: which team owns this ticket, how urgent is it, or should a result be reviewed?
That is the problem Jev is built for. TypeSafe AI calls it its first public System One Model: a model designed to return typed decisions and probabilities that software can use directly, rather than open-ended prose. Jev was introduced in September 2026 and is in early access. TypeSafe's announcement describes the approach.
The gap between an answer and an action
A conventional LLM can return JSON, call a tool, or follow a schema. That is often exactly the right solution. Still, the model generates a sequence of tokens; the application must decide whether the result is valid and what to do with it.
flowchart LR
    A["Application state"] --> B["Generative model"]
    B --> C["Generated output"]
    C --> D["Parse and validate"]
    D --> E{"Usable?"}
    E -->|Yes| F["Application action"]
    E -->|No| G["Retry or review"]
Jev changes the shape of the question. The developer defines possible answers before inference. The model returns a choice, score, or yes/no probability within that space. Code still owns the action.
flowchart LR
    A["Application state"] --> B["Jev"]
    C["Typed questions"] --> B
    B --> D["Decision and probabilities"]
    D --> E{"Application policy"}
    E -->|Confident enough| F["Act"]
    E -->|Uncertain| G["Review or ask again"]
This is not a claim that an LLM cannot produce structured output. It is a different optimization target: use a model for bounded judgments, then let ordinary code handle the workflow.
Three kinds of question
TypeSafe currently documents three decision primitives: Choice, Score, and Noul.
Choice: which option fits?
Imagine a support ticket: “The app crashes whenever I try to pay.” The application could ask which team should receive it: billing, engineering, account, or other.
A Choice returns a selected option, a probability for every option, and a confidence value. This illustrative response is not a live Jev result:
{
  "choice": "engineering",
  "probabilities": {
    "billing": 0.14,
    "engineering": 0.78,
    "account": 0.03,
    "other": 0.05
  }
}
The useful detail is not just engineering. The application can see that billing remains plausible and decide whether to notify both teams or request human triage.
Score: where on a scale does it fall?
Some decisions are ordered rather than categorical: severity, urgency, relevance, or quality. A Score rates the state against developer-defined levels, such as cosmetic, degraded but usable, and blocking. The result can fall between levels; the model also returns probabilities and confidence. The scale and its meaning belong to the application, not to a universal definition of “urgent.”
Noul: how likely is “yes”?
A Noul asks a yes/no question and returns the probability of “yes.” For example: “Does the evidence in this ticket support an automatic refund?” The code can then require review using a threshold chosen for that workflow.
The shared pattern is state in, bounded answer out. The application must still decide what risk it is willing to accept.
A concrete workflow: ticket triage
Consider a support system that needs to route and prioritize a ticket. Instead of asking one model to write an entire plan, the software can ask narrow questions and keep the workflow explicit.
flowchart TD
    A["Incoming ticket"] --> B["Choice: owning team"]
    A --> C["Score: urgency"]
    A --> D["Noul: needs human review?"]
    B --> E["Code checks answers and policy"]
    C --> E
    D --> E
    E -->|Routine and clear| F["Route automatically"]
    E -->|Urgent| G["Priority queue"]
    E -->|Ambiguous| H["Human triage"]
The model contributes judgment; the program remains responsible for thresholds, retries, escalation, audit logs, and final actions. That separation matters when a decision is made repeatedly inside production software rather than read once by a person.
Jev beside an LLM, not instead of one
Jev does not need to write the final response. A language model may still be the best tool for research, code, explanation, and conversation. Jev can sit at the points where the system needs to route or evaluate.
flowchart LR
    U["User request"] --> J1["Jev: classify intent"]
    J1 -->|Research| R["Research agent"]
    J1 -->|Coding| C["Coding agent"]
    J1 -->|Support| S["Support agent"]
    R --> L["LLM: generate response"]
    C --> L
    S --> L
    L --> J2["Jev: evaluate result"]
    J2 -->|Accept| P["Code applies policy"]
    J2 -->|Retry| L
    J2 -->|Escalate| H["Human review"]
A useful shorthand is LLMs generate, Jev judges, and code acts. It is an architectural pattern, not a rule every application should adopt. If a single structured-output LLM call already meets your latency, cost, and reliability targets, an extra model may add needless complexity.
Why not just ask an LLM for JSON?
JSON mode, tool calling, and constrained schemas are real alternatives. They can make generative outputs reliably parseable, and many applications should start there.
TypeSafe's argument is that formatting is only part of the problem. Jev is designed around parallel, typed decisions with probability distributions, whereas a conventional LLM generally generates tokens sequentially. The company also trains Jev with what it calls Reinforcement Learning for Calibrated Decisions (RLCD). These are TypeSafe's architectural and training claims, not proof that Jev will outperform an LLM in every workflow. Its technical announcement sets out the distinction and caveats.
The difference is worth testing where decisions are frequent, narrow, and latency-sensitive. It matters less where the task is open-ended writing or the model must invent an answer outside a predefined set.
Probability is not the same as correctness
Suppose a system reports an 80% probability for an outcome many times. Calibration means that, across comparable cases, roughly 80% of those outcomes should occur. A single 80% prediction can still be wrong.
TypeSafe also reports a confidence value. For a Choice, the docs describe it as a measure of how concentrated or spread out the option probabilities are. It is not a universal “safe to automate” switch. Your application needs thresholds appropriate to its own costs of false positives and false negatives. See TypeSafe's confidence guide.
That distinction tempers the phrase “no hallucinations.” A typed output can rule out an invalid option or malformed schema, but a well-typed decision can still be factually wrong. TypeSafe discusses limitations in its Jev 1.13 jaggedness notes.
What I would test before using it in production
- Accuracy on your own cases: compare Jev with your current structured-output LLM and a simple rules baseline.
- Calibration: group decisions by reported probability and check observed outcomes, not just top-choice accuracy.
- Escalation: decide what happens when the model is uncertain, options are incomplete, or input is out of distribution.
- End-to-end latency and cost: include network time, validation, retries, and human-review rates—not only model inference.
- Failure boundaries: keep authorization, irreversible actions, and business rules in deterministic code.
TypeSafe reports substantial speed and cost advantages on its own System One workflow evaluations, while noting how those benchmarks were designed and where bias might remain. Treat those figures as company-reported results until reproduced on workloads resembling yours. The published workflow evaluations are a starting point, not a substitute for a private test.
The bigger idea
Many production AI problems are not writing problems. They are routing, scoring, classification, verification, and gating problems wrapped in prompts.
Jev is an attempt to make those judgments a first-class software primitive. Its strongest use is not replacing every LLM call; it is making the boundary between generation, decision, and action explicit. Whether that improves your system is an engineering question worth measuring.
